Experiments have an important place in the development of science. They allow researchers to test whether an idea, an axiom, or a theoretically predicted phenomenon holds when it meets the real world. Many established scientific principles gained their authority through this process. Yet a result from one successful run is not, by itself, proof that an explanation is universally valid. A reading can be influenced by sensor noise, an uncalibrated instrument, a hidden software setting, a particular operator action, ambient conditions, or an analysis decision made after the data were collected.
For that reason, an experiment should be designed so that its result can be obtained again within clearly stated uncertainty and acceptance limits. In everyday scientific discussion, repeatable often means that an experiment can be run again with a consistent outcome. Measurement science makes a useful distinction: repeatability concerns successive measurements made under the same procedure, observer, instrument, location, and short time interval; reproducibility concerns agreement after specified conditions such as the operator, instrument, location, or time have changed.1 Both matter. Repeatability shows that a setup is stable enough to support a claim, while reproducibility tests whether that claim remains credible outside one narrow implementation.
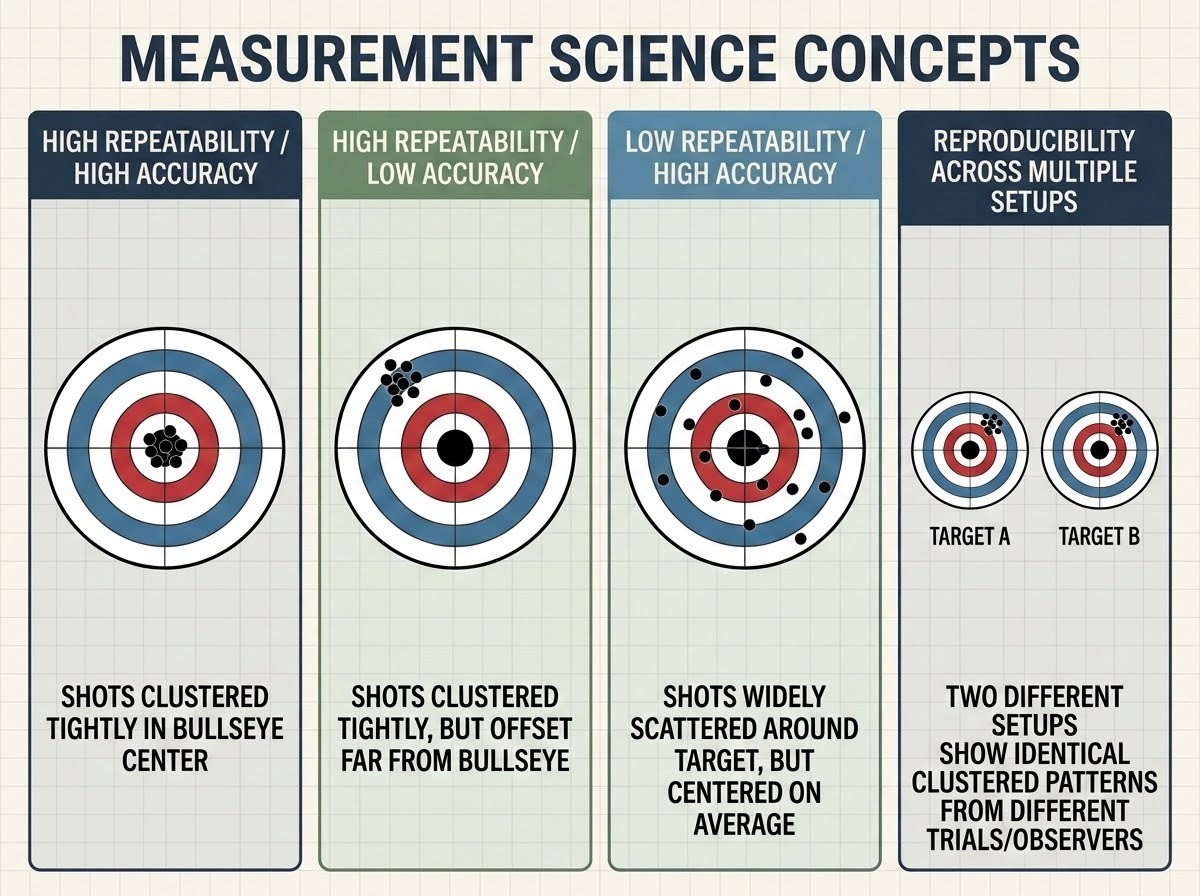
A convincing experiment therefore requires more than a favourable result. It needs a defined procedure, a clear description of the system under test, calibrated measurements, recorded assumptions, and data that allow others to inspect the reasoning. Independent replication is especially valuable because it can expose effects that a single team may not see. Confidence grows when several trials, researchers, or laboratories obtain compatible evidence using transparent methods.
Realizing Changes
One of the most important benefits of repeated experiments is that they reveal which changes actually matter. Repeating a test under deliberately varied conditions can produce observations that were absent in the first run. Those observations may identify a boundary of validity, suggest an improved model, or show that an apparently successful result depended on an uncontrolled variable.
This point is particularly clear in robotics and control engineering. Consider an inverted pendulum controlled to remain upright. A controller may balance the rod in one trial, but that outcome says little about its robustness until the experiment is repeated from different initial angles, with a defined payload, at different reference commands, or after a controlled change in friction or sensor noise. If the controller succeeds only in the first condition, the difference is not a failed repetition. It is evidence about the operating region of the system.
A disciplined test plan separates intentional factors from unwanted variation. Intentional factors may include controller gains, sample time, reference trajectory, payload, or disturbance level. Unwanted variation can include changes in supply voltage, encoder offset, temperature, network latency, loose mechanical couplings, or an undocumented firmware revision. The first group helps researchers learn how a system behaves. The second group must be measured, controlled, or reported so that it is not mistaken for a property of the algorithm.
Reducing Error Risks
Experiments are central evidence for scientific theories, but an error in the setup can distort that evidence. Repetition reduces the chance that a result reflects a one-off mistake, although it cannot eliminate every source of bias. Running the same uncalibrated sensor many times may yield a consistent result that is still wrong. This is why a repeatable workflow must address both random variation and systematic effects.1
In engineering laboratories, a golden configuration can reduce avoidable setup errors. It is a documented reference state for hardware, firmware, software, wiring, safety limits, sensor calibration, and test parameters. For a robotic platform, the configuration should identify the motor driver and firmware versions, encoder and IMU settings, controller update rate, filters, coordinate-frame conventions, payload, power source, and any mechanical adjustments. A photograph of the physical arrangement is often useful, but it is not a substitute for machine-readable parameter files and a dated calibration log.
Control experiments require special care because a small implementation difference can change a closed-loop result. A PID or LQR controller is defined by more than its gain values. The experimenter must also record the sampling period, actuator limits, anti-windup method, derivative filter, state-estimation method, reference signal, initialization rule, and safety shutdown criteria. For a MIMO system, the ordering and scaling of input and output channels must be explicit. Without this information, another researcher can reproduce the apparent controller structure while implementing a materially different experiment.
Measurement quality matters as much as controller design. NIST distinguishes accuracy from precision and recommends reporting uncertainty in terms such as standard uncertainty, combined standard uncertainty, or expanded uncertainty when appropriate.1 In practical control work, researchers can start by reporting the sensor resolution and calibration status, then quantify run-to-run dispersion for the chosen performance measures. This avoids overstating what a single trace can prove.
Verification of Results
Verification requires more than collecting more copies of the same data. It requires checking whether the claim survives repeated trials under a protocol that specifies what is held constant, what is varied, and what counts as success. A larger number of runs can increase confidence in the estimated behaviour of a system, but repetition alone cannot establish validity if every trial shares the same hidden bias. A strong verification plan combines repeated trials with independent review, transparent data handling, and, when feasible, reproduction under changed conditions.
For a feedback-control experiment, the raw result should be transformed into predeclared metrics rather than judged from a visually appealing plot. If the reference is (r(t)) and the measured output is (y(t)), the tracking error is (e(t)=r(t)-y(t)). Depending on the objective, useful metrics can include peak error, overshoot, settling time, integral absolute error (|e(t)|,dt), RMS tracking error, control effort, energy use, saturation time, and the number of safety or stability violations. The chosen metrics should be evaluated across all valid trials, with exclusions explained.
Robotics validation follows the same logic at a larger system level. A robot’s observed performance is the combined effect of sensing, estimation, planning, actuation, software, and the environment. Rigorous validation therefore needs performance metrics, test methods, datasets, and protocols that relate results to the intended application rather than to an abstract claim.2 For example, a manipulation system should report the object set, starting poses, lighting or scene conditions, task success definition, recovery behaviour, and the number of attempts. A mobile robot should record the map or route, payload, floor condition, localization source, speed profile, and intervention rules.
Independent replication adds a valuable stress test. A second team may use the same experimental specification while changing the operator, physical unit, laboratory, or time of test. If results remain compatible within stated uncertainty, the original conclusion gains wider support. If they differ, the documented protocol provides a starting point for investigating whether the cause lies in the plant, the measurement chain, the software, or the analysis.
Reusable Repeatable Experiment Setups
Advances in mechatronics, automation, and digital infrastructure have made repeatable experimentation easier to organize. Especially, the fact that repeated experiments have become more important has led to the birth of a new type of experiment system called remotely accessible experiments.
Reusable experimental systems provide a controlled physical platform on which students and researchers can compare methods without rebuilding the entire apparatus for every study. Their value is not that they remove engineering uncertainty. Their value is that they make the configuration, interface, and reset procedure explicit enough for the uncertainty to be examined.
Some systems in automatic-control research are especially useful for this purpose:
Linear Inverted Pendulum
A linear inverted pendulum is a classical benchmark for demonstrating how feedback control stabilizes an unstable, nonlinear physical system. It exposes important real-world effects that a simple simulation may hide, including actuator limits, friction, sensor noise, quantization, delay, and differences between the mathematical model and the physical plant. ACROME’s Linear Inverted Pendulum is designed for testing advanced feedback-control algorithms and provides encoder and potentiometer feedback, a controller, and example source code.3
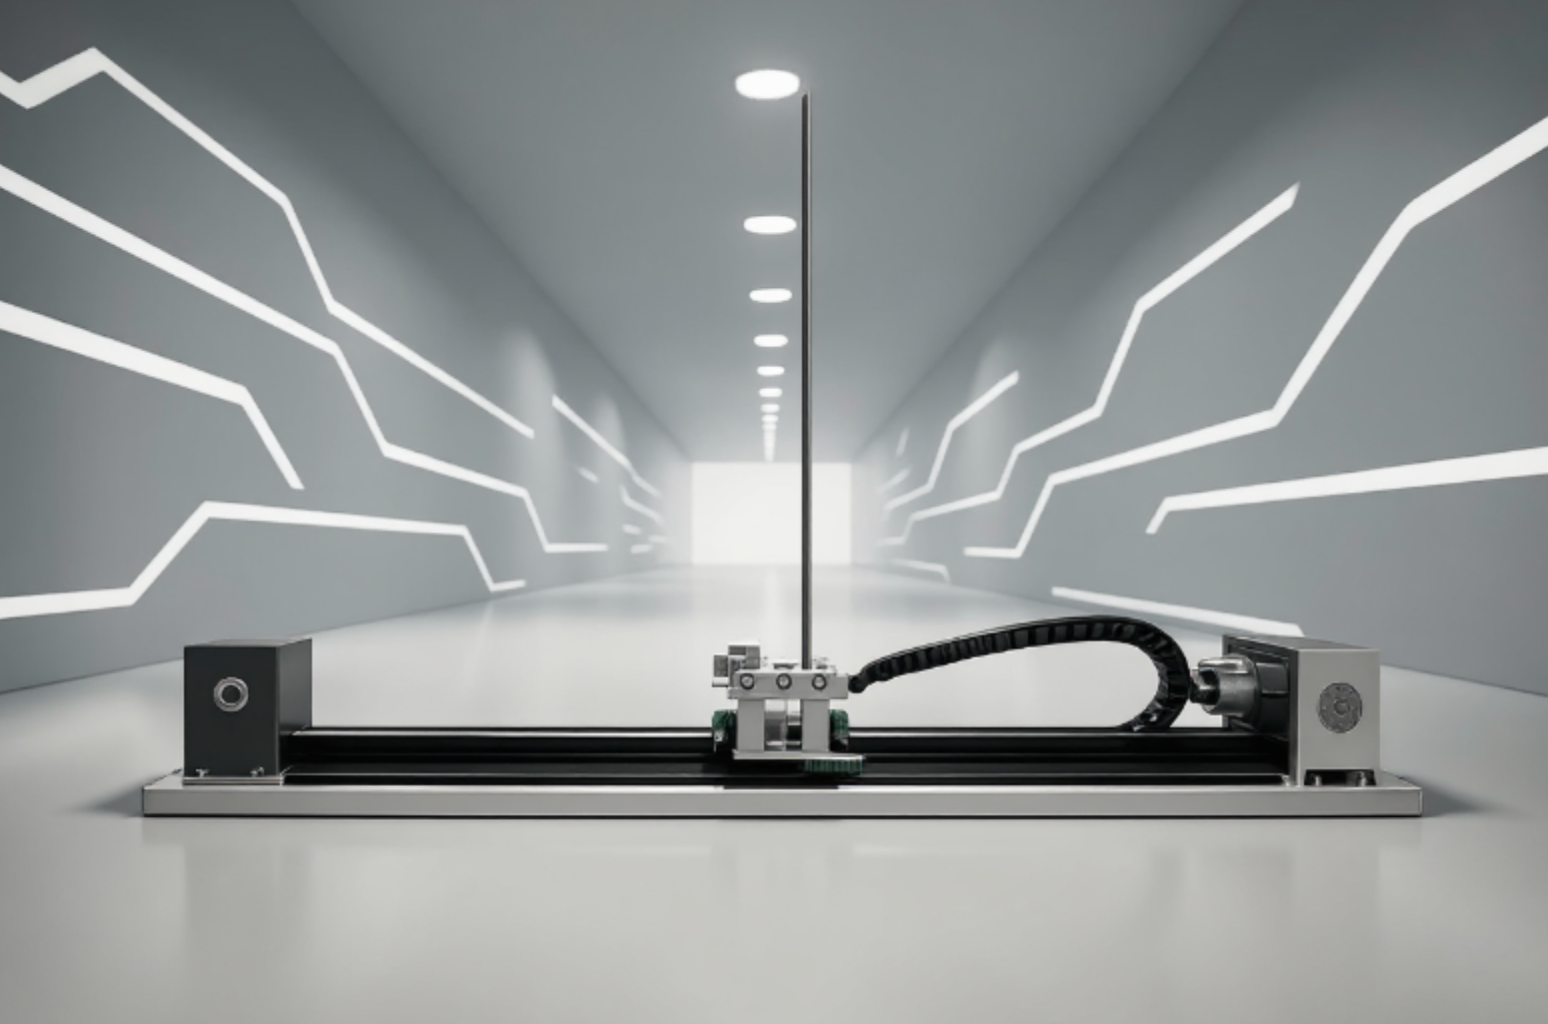
A repeatable pendulum experiment should define the rod configuration, cart starting position, initial angular range, reference profile, controller parameters, sampling period, safety bounds, and reset procedure. Researchers can then compare, for example, PID, state-feedback, observer-based, or nonlinear control approaches using the same metrics and operating conditions. The resulting comparison is more credible than a demonstration based on one carefully selected successful run.
X-DoF Helicopter and 3-DoF Copter Systems
X-DoF helicopter platforms are frequently used to study flight dynamics, coupled motion, and real-time control. In a current 3-DoF copter implementation, the pitch, roll, and yaw dynamics provide a compact MIMO control problem in which propeller thrust, cross-coupling, state estimation, and actuator constraints all influence the outcome. ACROME’s 3-DoF Copter includes encoder and IMU feedback, open-source examples, digital-twin files, and support for hardware-in-the-loop work; its starter materials include an LQR-based example.4
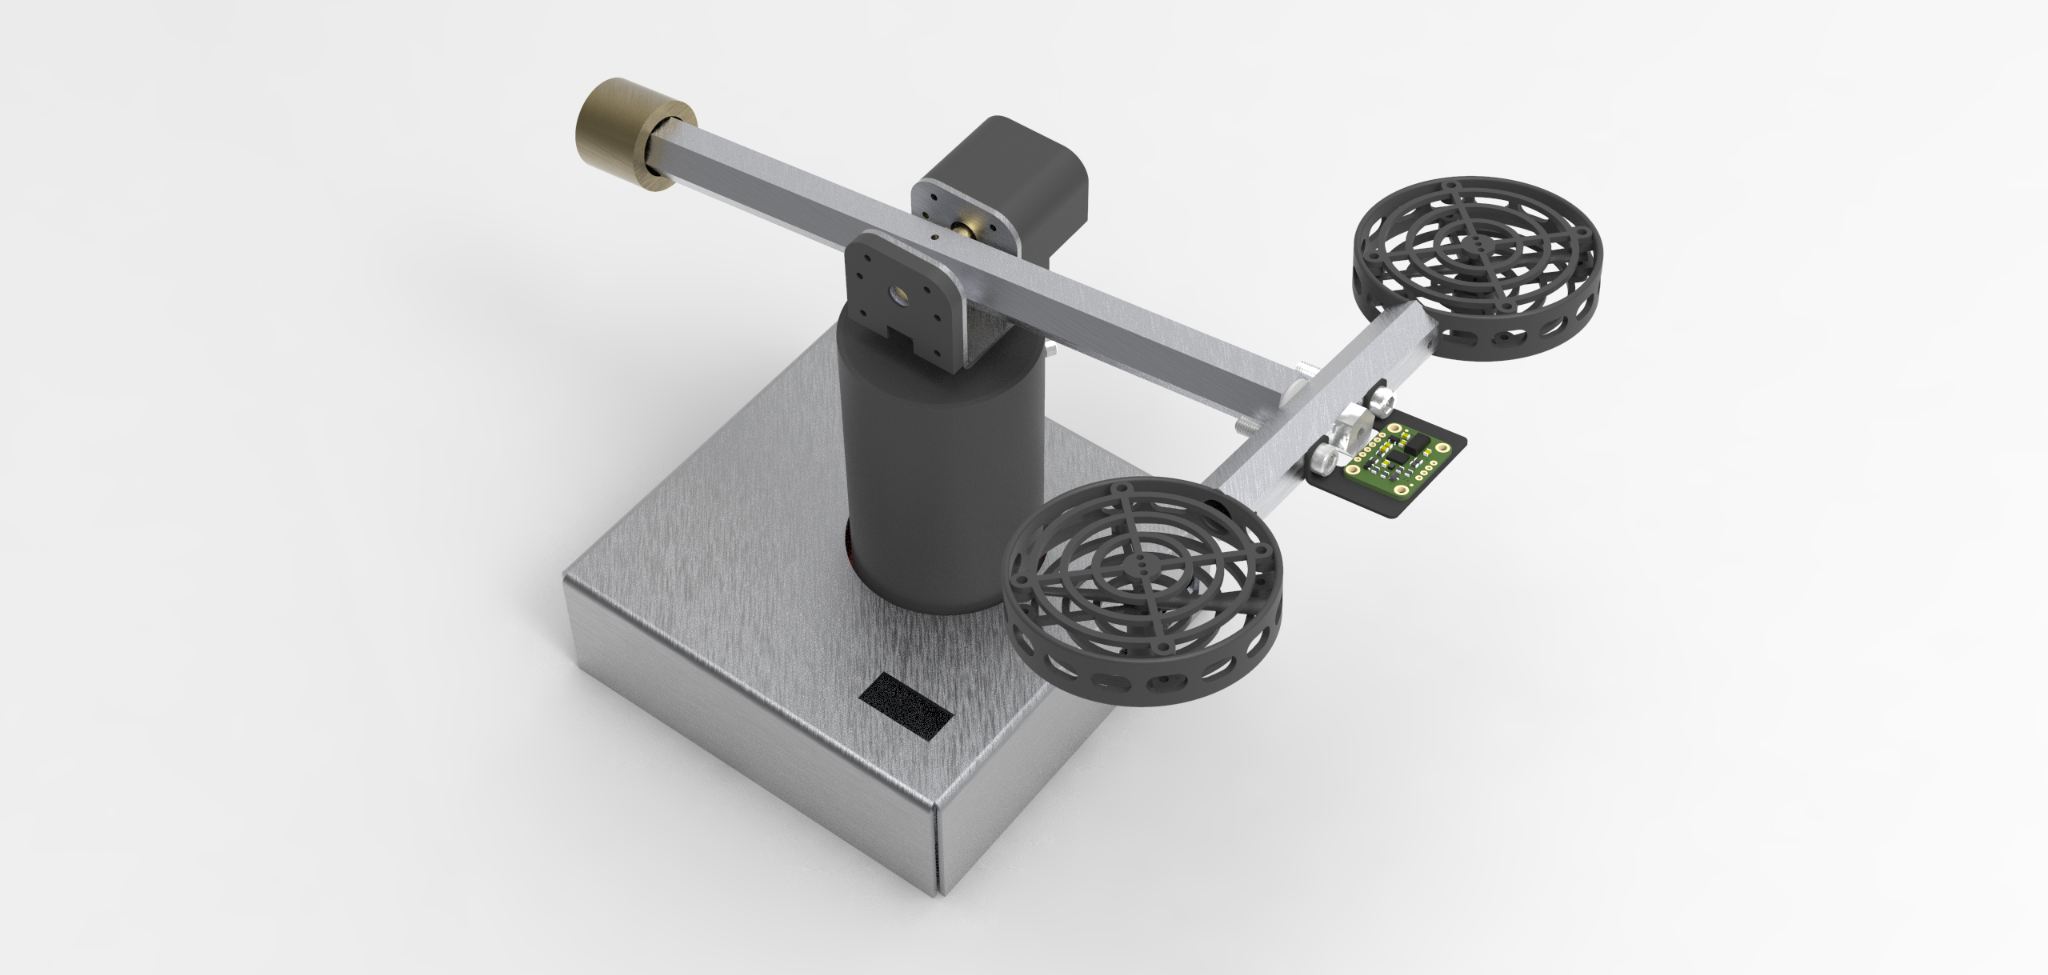
For such a system, reproducible validation means recording more than the controller matrix. The report should state the selected axes, motor commands, propeller condition, sensor fusion or filtering approach, IMU calibration, operating range, disturbance method, and controller execution rate. It should also state whether the reported angles are directly measured, estimated, or derived. Repeating each trajectory from a controlled initial pose makes it possible to distinguish a true control improvement from a transient advantage created by a favourable starting condition.
Contribution of Remotely Accessible Laboratories to Repeatable Experiments
Remotely accessible laboratories can extend the benefits of reusable testbeds when they are designed around a documented experimental workflow. A remote laboratory allows users to submit or run algorithms on real hardware while preserving a common physical platform, defined interfaces, and logged data. ACROME describes its Remote Lab as a service through which users can connect to their local physical robotic and mechatronic systems and run algorithms in real time over the internet.5
This model can reduce avoidable differences between student or researcher setups. Instead of each participant assembling a separate apparatus, a shared platform can enforce a known hardware configuration and present a common test scenario. A digital twin can support model development, parameter exploration, and pre-usage checks; physical experiments remain necessary to examine friction, actuator dynamics, sensing limitations, and other effects that are not fully represented by the model.
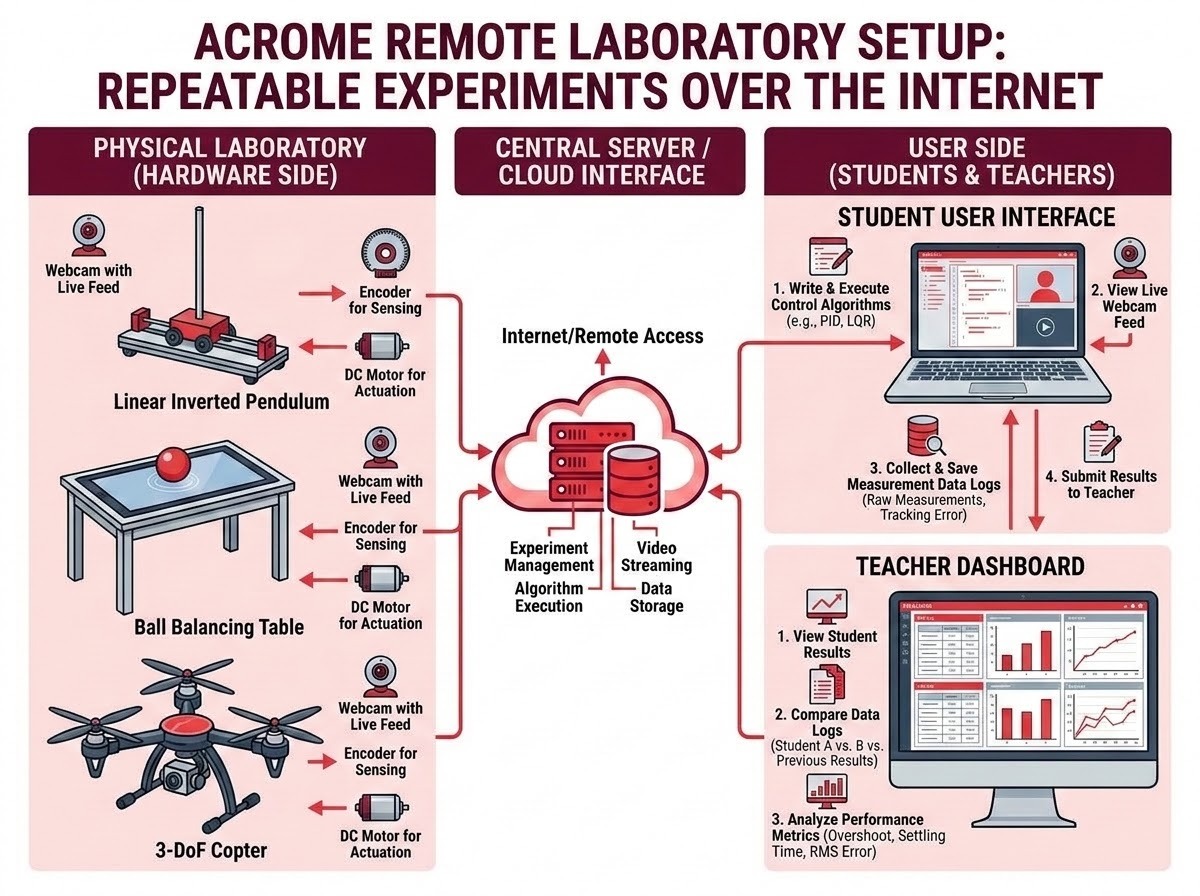
Remote access does not make an experiment repeatable by itself. A sound remote-lab protocol still needs a reservation or execution record, an explicit initial state, a physical reset between trials, a stated time window, versioned code and parameters, safety limits, and automatic storage of raw data. When those elements are present, remote laboratories can make repeated trials more accessible and make it easier for multiple users to compare results on the same equipment.
Conclusion
Repeatable experiments are a foundation of credible science because they turn a promising observation into evidence that can be inspected, challenged, and strengthened. In robotics and control systems, this discipline is essential: a successful trajectory or a stable demonstration is meaningful only when the test conditions, measurements, code, and performance criteria are clear enough to be examined again.
The practical goal is not to force every run to produce an identical trace. Physical systems vary, measurements carry uncertainty, and robust engineering requires understanding that variation. The goal is to create experiments whose conditions are controlled or recorded, whose performance is measured consistently, and whose results remain interpretable when another researcher repeats the work. Well-designed reusable platforms, transparent protocols, and thoughtfully managed remote laboratories provide a practical path toward that standard.
FAQ: Experimental Protocol and Best Practices
- How do I verify if my controller tracks the desired motion?
Apply the same reference trajectory over multiple runs after a defined reset. Retain evidence such as the time-stamped reference, output, control input, tracking-error trace, and trial ID.
- How can I ensure performance holds under stated disturbances?
Repeat the protocol at predeclared disturbance levels rather than selecting a convenient case after testing. Retain evidence such as the disturbance profile, initial state, and performance summary for every run.
- How can my team ensure others can recreate our results?
Version your source code, controller parameters, sampling configuration, and hardware configuration. Retain evidence such as the code commit, parameter file, bill of materials, and calibration record.
- How do I determine if a performance difference is meaningful?
Compare distributions across runs and report variation, rather than relying on a single best trace. Retain data such as the mean or median, standard deviation, sample count, and details on failures and exclusions.
- What is the difference between repeatability and reproducibility?
Repeatability concerns successive measurements made under the same procedure, observer, instrument, location, and short time interval. Reproducibility concerns agreement after specified conditions—such as the operator, instrument, location, or time—have been changed.
- What is a "golden configuration"?
A golden configuration is a documented reference state for hardware, firmware, software, wiring, safety limits, sensor calibration, and test parameters used to reduce avoidable setup errors.
- Why is independent replication important?
Independent replication can expose effects that a single team may not see, ensuring that scientific claims remain credible outside of one narrow implementation.
Repeated work also makes contradictions visible. A mismatch between the measured response and a hypothesis may reveal an unmodelled delay, actuator saturation, cross-axis coupling, or a faulty assumption about the plant. These findings can lead to an alternative hypothesis and a better experiment. Scientific progress often begins when a well-documented result refuses to behave as the first explanation predicted.
- How do x-DoF helicopters support repeatable testing of experimental flight control algorithms?
Here are some reasons why x-DoF Copters are suitable for testing the flight control algorithms:
- Controlled physical plant: The copter constrains the aircraft-like motion to defined degrees of freedom, allowing you to test flight-control logic without conducting repeated free-flight tests. The system provides pitch/yaw feedback through encoders and an IMU.
- Repeatable system identification: You can characterize the plant by applying controlled rotor inputs and measuring responses. The accompanying article specifically describes identifying parameters such as damping and thrust coefficients.
- Real-time algorithm deployment: Users can create their own real-time control algorithms, rather than being limited to the manufacturer's controller. MATLAB/Simulink integration is explicitly supported.
- Simulation → hardware workflow: A controller can first be evaluated against the supplied model/digital twin, then deployed to the physical system. There is the typical workflow: System identification → controller design → simulation → real-time execution → telemetry analysis.
- Quantitative comparison: You can repeat the same reference commands and compare commanded versus actual responses, including measures such as settling time, overshoot and disturbance rejection.
- Repeatable sensor experiments: The modular I/O capability can be used to characterize encoder and IMU noise, which is useful when evaluating estimators such as Kalman filters under consistent test conditions.
References
[1] NIST Technical Note 1297, Appendix D.1: Terminology
[2] NIST: Measurement Science for Robotics and Autonomous Systems Program
[3] ACROME Linear Inverted Pendulum
[5] ACROME: Enriching Engineering Education with Digital Twins and Remote Labs
Author


